


Requesty
Value Proposition & Features
https://router.requesty.ai/v1) and one key to access hundreds of models from providers such as OpenAI, Anthropic, Google, Mistral and others, allowing unmodified OpenAI SDK calls after swapping base URL, key, and model name.
[e4o0x7]
[^296feu]
[wti18u]
[^582k3y] It routes requests to upstream providers while handling automatic failover and exposes per-endpoint pricing, context windows, and live routing/latency data in its model catalogue and rankings.
[y61gvv]
[^xo83j9] [^zby20p] [^5w2o8g]- Intelligent Model Routing routing and automatic failover across providers/endpoints, including cost-, latency- and availability-aware policies and mid-stream fallbacks. [3cirso] [6a4elw] [^xo83j9] [^7mzzyi] [^hs33uh]
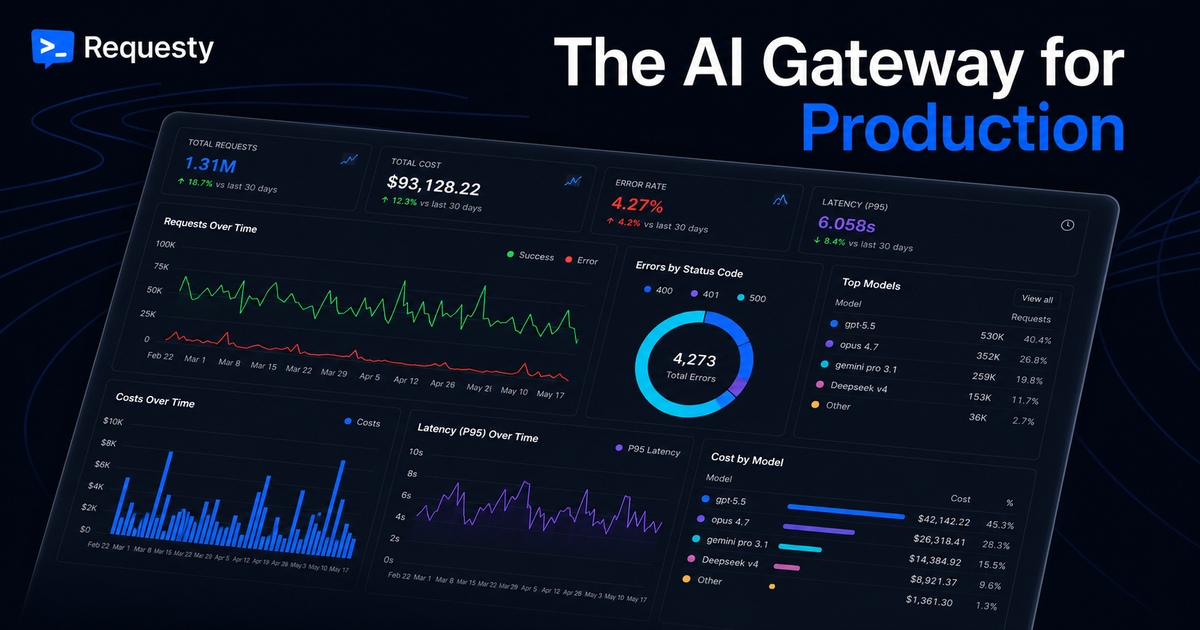
- Real-time analytics and observability dashboards for spend, latency, token usage and cache impact, plus an Overview page with breakdowns by model, app, group, user and API key. [6a4elw] [^s2j0x1] [^hnz80i] [^b8wsgm] [^x1vugh]
- EU routing and data residency via an AWS Frankfurt endpoint (
router.eu.requesty.ai), with EU-only logging options and documented subprocessors and retention defaults. [3cirso] [^ic1dwg] [^5hs925] - Public model rankings and performance benchmarks showing provider latency, error incidents, model share, cost and routing-policy improvements. [^p69lom] [^7mzzyi] [^0n5fvm] [^5w2o8g] [^hs33uh]
Product Roadmap / Announcements
- 2026-08-22 – Multiple new endpoints added with pricing and context windows: Qwen/Qwen3.5-35B-A3B and Qwen/Qwen3.5-27B on DeepInfra, gemma-4-31B-it on DeepInfra, gemini-3.5-flash-lite on Google Gemini API, deepseek-v4-flash-0731 on DeepInfra, and new OpenAI Responses/OpenAI Inc. GPT-5.6-sol and GPT-5.6-luna variants, each with documented token prices and 10% discounts vs provider list rates. [^qs1rzw] [^mdehe0] [^s0hs57] [^2qd5oy] [^bf9rvd] [^69bgfv] [^ow0h36] [^7wczsb]
- 2026-08-21 – Anthropic Claude Opus 5 endpoints added (including Bedrock variants) with published pricing, discounts, and caching details, plus context window of 1M tokens and maximum output of 128K tokens. [^j4bvhj] [^w9nzxd] [^gn4u4f]
- 2026-08-11 – Requesty announces a new Overview page showing AI usage across organizations, with drill-down by models, apps, groups, users and API keys, via social posts. [^y664ca] [^hnz80i] [^x1vugh]
- 2026-07-30 – Requesty announces reduced prices for OpenAI GPT-5.6 Luna and GPT-5.6 Terra on its platform, later extended to EU endpoints with additional discounts. [^y664ca] [^0u1et5] [^ow0h36]
- 2026-07-25 – Blog post “Opus 5, Grok 4.6, GPT-6 rumors: shipping through the model release treadmill” outlines their focus on staying current with rapid model releases and maintaining routing-focused integrations rather than frequent client rewrites. [^s38aky] [^0d2hfw] [^8eh2sm]
Recent Developments
- Stripe’s talks to acquire OpenRouter for around $10 billion sparked broader interest in AI routing; Requesty stated that at least 25 companies had approached it in recent weeks about investments, acquisitions or partnerships, according to a report citing CEO Thibault Jaigu. [^8xcbip] [^sf7xmq] [^ssi6xn]
- Requesty’s blog and rankings pages introduced “The State of Production AI,” publishing live data on model share, cost and speed across 40 models and 32 providers, including token share statistics and cost metrics. [^5w2o8g] [^qt9li1] [^v3q6vh]
History and Origin Story
Fundraising History
| Round | Date (approx/announced) | Amount | Lead investor |
| Seed | 2025-09-26 (announced) | $3M | 20VC |
| – | – | – | – |
| Sources for Table: [^nzm3pv] |
- 20VC [^nzm3pv]
- Insiders Ventures [^nzm3pv]
- Tapestry VC [^nzm3pv]
- Tiny Supercomputer [^nzm3pv]
Notable Team Members
Market Sizing
Category, Market Size, and Category Growth
Pricing
| Tier | Price | What you get |
| Free | $0 | 200 requests/day on free models, routing, caching, fallbacks, EU residency, no card required. |
| Pay as you go | 5% markup on model cost | Full catalogue access, bring-your-own-keys, all routing policies, observability, MCP gateway, spend limits, EU data residency. |
| Enterprise | Custom | SSO, RBAC, audit logs, model whitelists, guardrails, PII detection, custom SLAs. |
| Sources for Table: [3e598v] [j6ppel] |
Revenue Trajectory Estimates
Competitive Landscape
Who it’s for, who it’s not for
Viable Alternatives
- Kong AI Gateway / Bifrost / Vercel AI Gateway / OrcaRouter – Various gateways that offer managed or self-host options with different focuses (governance, cost, edge integration, no markup) and are frequently mentioned in 2026 comparisons as Requesty or OpenRouter alternatives. [1y1tj0] [9qy7g8] [dn7haa] [gd5q2k] [j0at06] [dlwr19] [cfwm7x]
Competitor Table
| Competitor | Description |
| OpenRouter | Hosted OpenAI-compatible routing layer that exposes many models via a single endpoint with provider routing, failover and a per-token platform fee, widely referenced as a primary alternative in LLM gateway comparisons. |
| Portkey | Managed and open-source AI gateway focused on governance, observability and cost monitoring, covering 1,600+ models across 45+ providers with both OSS core and hosted control plane. |
| LiteLLM | MIT-licensed open-source proxy and library that lets teams call 100+ LLMs via an OpenAI-compatible format, typically self-hosted for maximum control. |
| Cloudflare AI Gateway | Managed edge AI gateway integrated into Cloudflare, providing dynamic routing, retries, analytics, logs and cost metrics, aimed at teams already using Cloudflare infrastructure. |
| Kong AI Gateway | AI gateway built on Kong’s API infrastructure, offering strong governance and policy controls with options for managed and self-host deployment, listed among top gateways for infrastructure-level control. |
| Bifrost | Low-overhead, fully self-hosted Go-based LLM gateway (Apache 2.0) with routing, caching and observability features, recommended for enterprises needing OSS and self-host governance. |
| Vercel AI Gateway | Managed AI gateway that routes to hundreds of models across 45+ providers with zero markup on tokens, positioned as a multi-model routing and cost control layer. |
| OrcaRouter | Managed LLM router pitching itself as a Requesty alternative with no per-token markup, 200+ models, high routing-accuracy scores, prompt grading and fast failover. |
| Sources for Table: [1uz2hn] [1y1tj0] [9qy7g8] [dn7haa] [qh05bx] [cfwm7x] [dlwr19] [amom2i] [uzl69h] [j0at06] [^myjiu5] |
Sources
[y61gvv] claude-opus-5 - Google LLC (Vertex AI) - Requesty [6]: List Models - Quickstart - Requesty Docs
[35799t] Anthropic PBC claude-opus-5 API Pricing & Cost - Requesty [9]: OpenAI Inc. gpt-5.4 [10]: OpenAI Inc. gpt-5.6-luna
[j8zk0q] DeepInfra Inc. deepseek-ai/DeepSeek-V4-Flash [14]: AWS Bedrock claude-opus-5 API Pricing & Cost - Requesty [15]: OpenAI Responses gpt-5.2
[uzl69h] Best OpenRouter Alternatives in 2026: Routing, Control & Fit [22]: OpenRouter Alternatives 2026: LLM Gateway Comparison for ...
[j0at06] AI Model Routing Platforms Expand 'Bring Your Own API Key' Options as Businesses Seek Cost Control
[dlwr19] Top 10 Vercel AI Gateway Alternatives for LLM Apps (2026) [27]: Best LLM Gateways in 2026: Top Picks Compared
[cfwm7x] Requesty Alternatives 2026: Skip the 5% on Every Token [29]: 9 OpenRouter Alternatives for Multi-Model AI in 2026 | DigitalOcean
[6j3373] gpt-5-pro: Compare 1 Provider, API Pricing & Performance [34]: meta-llama/Meta-Llama-3.1-8B-Instruct-Turbo
[13jroc] gemini-3-flash-preview [37]: Fireworks AI kimi-k3 API Pricing & Cost - Requesty [38]: AWS Bedrock claude-opus-5 API Pricing & Cost [39]: Requesty (@RequestyAI) / Posts / X
[p9un7l] Google LLC (Gemini API) gemini-2.5-pro [41]: OpenAI Inc. gpt-5.1 [42]: AWS Bedrock claude-opus-5 API Pricing & Cost [43]: Fireworks AI deepseek-v4-pro-0813 API Pricing & Cost [44]: Thibault Jaigu's Post - Founding GTM Lead [45]: Slawomir Baran Johansen's Post [46]: Interesting piece of analysis by Requesty on this year's AI ...